Repository navigation
[slime] Support score centering - #2405
Merged
Merged
Conversation


tongyx361
added a commit
to verl-project/verl
that referenced
this pull request
Oct 1, 2026


…ypass-mode REINFORCE (#8010) ### What does this PR do? Adds score centering ([Marek & Ryabinin, 2026](https://arxiv.org/abs/2609.20807)) to the bypass-mode REINFORCE loss. Implements RFC #8009. Under training-inference mismatch the policy gradient carries a drift term `E_q[R] * E_q[∇log p]` that distills the trainer toward the (quantized / stale) sampler. Score centering subtracts the expected score under the sampler from each token's score: an additive, hyperparameter-free correction that is a no-op on-policy and composes with token-level TIS / IcePop. The sampler's top-k head (k = 128 in the paper; 32 also matches) is stored per generated token and the tail is modeled as the trainer's tail rescaled to the sampler's tail mass, so the trainer only evaluates the k head log-probs. Scope: vLLM rollout + FSDP actor on the v1 (TransferQueue) trainer in `sync`, `colocate_async` and `separate_async` modes, single-turn agent loop, `top_p=1`, `top_k=-1`, `logprobs_mode=processed_logprobs`, no fused kernels. `RolloutCorrectionConfig` pins score centering to bypass REINFORCE with token-level or no IS, `RolloutConfig` pins `topk_log_probs` to the vLLM sampling distribution, `validate_config` checks the driver and actor sides agree and that the run is v1 + FSDP + vLLM without distillation, and the FSDP engine rejects fused kernels; SGLang / TRT-LLM, Megatron / veomni / torchtitan, the legacy trainer, `top_p<1` replay (as in slime#2406) and disk spill are out of scope. Prior art: slime merged the same method on 2026-09-23 (THUDM/slime#2405, #2406, Megatron + SGLang). Commits are one per module (config, correction math, loss integration, vLLM head, v1 data path, trainer/FSDP wiring, docs) plus one cleanup commit and one review-fix commit. Reproduction of the paper's Fig. 4 (left) with an fp8 sampler is in the Test section. ### Checklist Before Starting - [x] Search for similar PRs: https://github.com/verl-project/verl/pulls?q=is%3Apr+score+centering , https://github.com/verl-project/verl/issues?q=centering — none besides RFC #8009. - [x] Title format `[rollout, vllm, algo, fsdp, trainer, doc] feat: ...` ### Test CPU (`pytest -q -p no:cacheprovider`, CPU-only venv, 69 passed over the 5 test files this branch touches or adds): - `tests/trainer/ppo/test_score_centering_on_cpu.py` (new): presets, `RolloutCorrectionConfig` / `RolloutConfig.topk_log_probs` rejections plus `max_logprobs` injection, and the driver-side `validate_config` rejections; chunked top-k log-probs equal `log_softmax.gather` with matching gradients; correction is zero on-policy; gradient equals exact full-vocab centering when `k = V` and matches the paper's tail model for `k < V`; drift cancels under a constant reward; TIS / IcePop weight rule and `alpha = rho f(1/rho)` composition; head layout helper and padding template; flat-logprobs head extraction (bitwise equal to vLLM's dict view, skipped without vLLM); the fully async client carries the head across partial-rollout resumes; REINFORCE adds `A * sc_correction`; bypass dispatch; logits processor output; real `ppo_loss` end to end on a ragged batch against a hand-computed loss and metrics; on-policy (sampler head = trainer head) the loss and its gradient are bitwise unchanged. - `tests/workers/test_score_centering_wiring_on_cpu.py` (new): the engine keeps `logprobs_from_logits` out of in-place mode when score centering is on (its backward would otherwise overwrite the logits the chunked gather saved). - `tests/experimental/agent_loop/test_agent_loop_extra_fields_schema_on_cpu.py`, `tests/trainer/ppo/v1/test_agent_loop_tq_on_cpu.py`, `tests/trainer/ppo/v1/test_trainer_base_on_cpu.py` (extended): `as_dict` promotion and multi-turn rejection, TQ postprocess (store, validate-skip), v1 `_update_actor` flag. - Existing `tests/trainer/ppo/test_rollout_corr*.py`, `tests/utils/test_padding_on_cpu.py`, `tests/workers/test_distillation_topk_symmetry_on_cpu.py` unchanged and passing. GPU, 2x RTX PRO 6000 (vLLM 0.29.0, torch 2.13, TP=1 replicas, FSDP DP=2): - v1 smoke, Qwen2.5-0.5B-Instruct on GSM8K, `topk_log_probs=128`, SC + token-TIS, 2 steps: 3.9 s/step, `actor/sc_sampler_head_mass=0.9986`, `actor/sc_train_head_mass=0.9986` (the paper reports >99.9% for k=128), `rollout_is_mean=1.00003`, `actor/sc_correction=-2e-4` with the bf16 sampler. - **Paper Fig. 4 (left) analogue**: Qwen3-0.6B on Countdown (official task port, 64 held-out prompts), fp8 W/A + fp8 KV vLLM sampler vs bf16 FSDP trainer (the paper uses int8; vLLM has no online int8), REINFORCE with group-centered ±1 reward, SGD lr 1e-2, no gradient clipping, 64 prompts x 8, one optimizer step per batch, 400 steps, one seed per arm. Needs #8064 for the fp8 weight sync. Training accuracy = (`critic/score/mean` + 1) / 2, 10-step moving average in the plot. 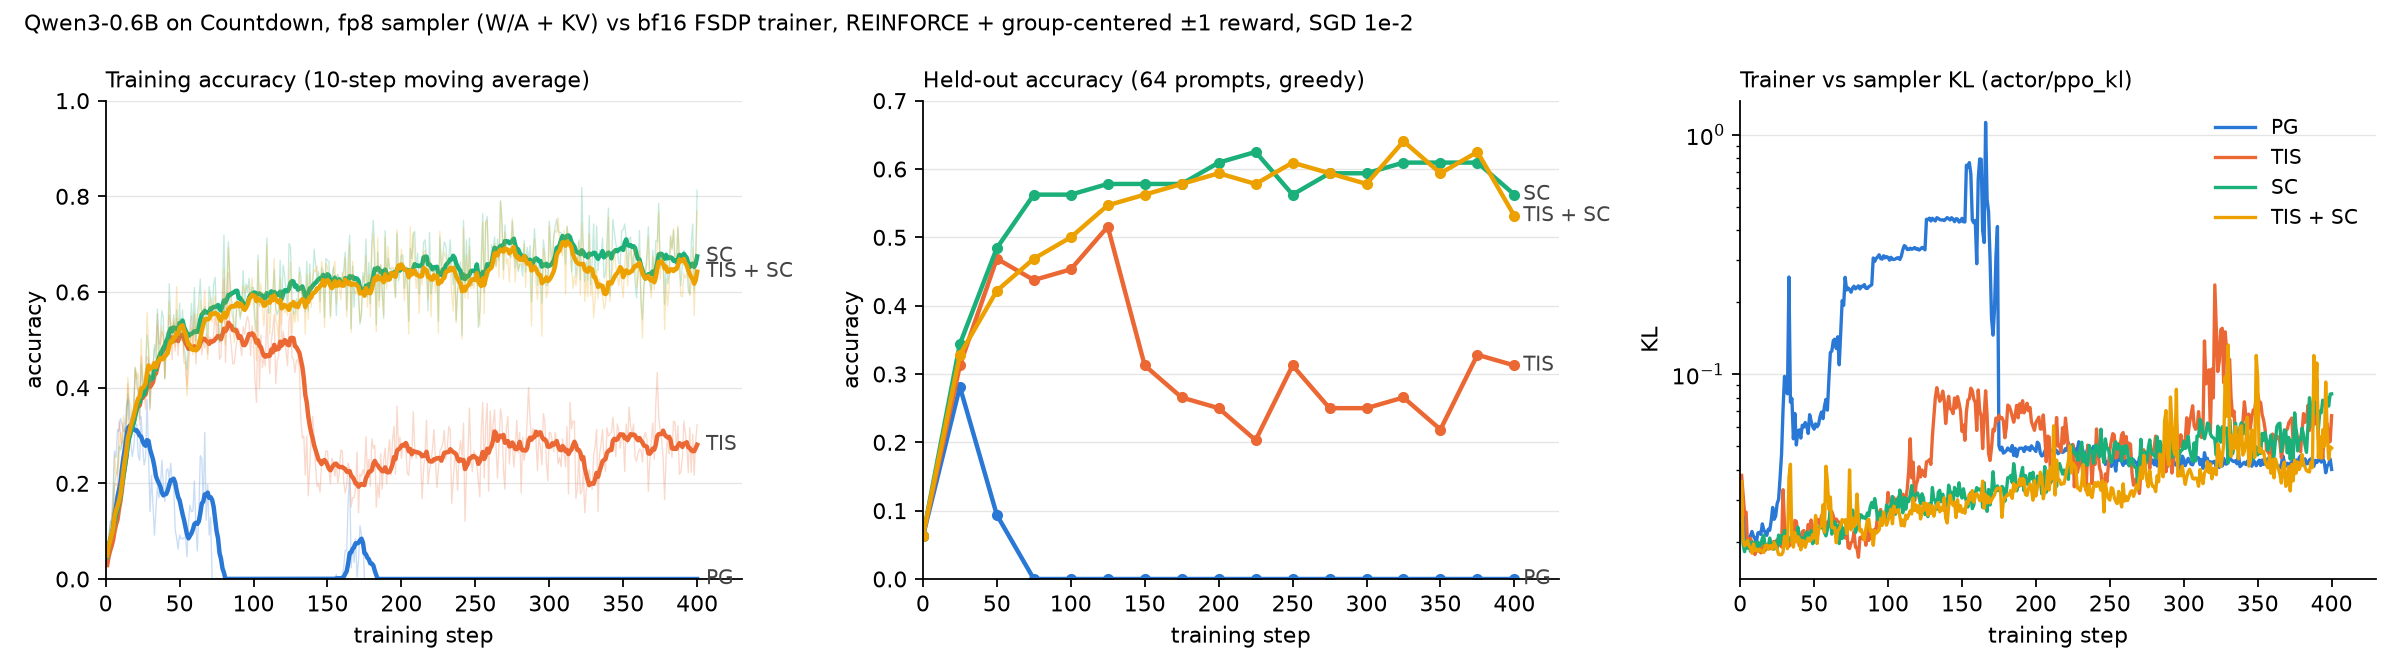 | mode (`algorithm.rollout_correction`) | train acc, mean of last 50 steps | held-out acc max / final | `actor/ppo_kl` max | outcome | |---|---|---|---|---| | `bypass_pg` | 0.00 | 0.28 / 0.00 | 1.13 | collapses at step 72 | | `bypass_pg_token_tis` | 0.28 | 0.52 / 0.31 | 0.24 | peaks at step ~80, degrades from step ~130 | | `bypass_pg_sc` | 0.67 | 0.63 / 0.56 | 0.08 | stable | | `bypass_pg_token_tis_sc` | 0.65 | 0.64 / 0.53 | 0.13 | stable | Same ordering as the paper (SC alone ≈ SC composed > TIS > PG). Per-step cost on this setup: 25 s (sc) / 21 s (tis_sc) vs 14–17 s (pg) / 11 s (tis), from the k=128 head retrieval and the chunked top-k backward. `sc_sampler_head_mass` and `sc_train_head_mass` stayed ≥ 0.9996. The four arms ran on the dict-based extraction; after switching to flat logprobs (review round 1) a 3-step fp8 re-run gave the same metrics (`ppo_kl` 0.022-0.035, head masses ≥ 0.9997) at 14-16 s/step instead of 19-29 s. ### API and Usage Example ```yaml actor_rollout_ref: rollout: calculate_log_probs: true topk_log_probs: 128 # new: sampler top-k head per generated token (vLLM) actor: use_fused_kernels: false policy_loss: loss_mode: bypass_mode rollout_correction: # actor-side mirror, or RolloutCorrectionConfig.bypass_pg_token_tis_sc() bypass_mode: true loss_type: reinforce rollout_is: token rollout_is_threshold: 2.0 score_centering: true # new algorithm: rollout_correction: bypass_mode: true loss_type: reinforce rollout_is: token rollout_is_threshold: 2.0 score_centering: true ``` Presets: `RolloutCorrectionConfig.bypass_pg_sc()`, `bypass_pg_token_tis_sc()`, `bypass_pg_token_icepop_sc()`. Metrics: `actor/sc_correction`, `actor/sc_sampler_head_mass`, `actor/sc_train_head_mass`. Docs: `docs/algo/rollout_corr.md` §8. Example: `examples/rollout_correction/run_qwen2_5_0_5b_score_centering_fsdp.sh`. The actor-side `policy_loss.rollout_correction` mirror is needed because the actor worker reads its own copy of the policy-loss config; `validate_config` checks the two sides agree. ### Design & Code Changes - `RolloutConfig.topk_log_probs`: the vLLM server requests `SamplingParams(logprobs=k, flat_logprobs=True)` (was hard-coded `0`), raises `max_logprobs` like the distillation teacher, reshapes the flat lists into int32 / float32 arrays and returns them in `TokenOutput.extra_fields`; the sampled-token log-prob comes from the same arrays. Validation rollouts do not request the head, and the request key is only sent when a head is wanted. - Batch keys `rollout_topk_ids` (int32) / `rollout_topk_log_probs` (fp32) laid out over the full sequence like `teacher_ids` / `teacher_logprobs` (row `P-1+r` holds response token r's head): `AgentLoopOutput.as_dict` promotes them and TransferQueue stores them unpadded; the padding template fills a uniform dummy head. - `verl/trainer/ppo/score_centering.py`: chunked, vocab-parallel-aware autograd function for full-vocab-normalized log-probs at the head ids (bounded fp32 workspace, recompute in backward, ported from slime); the head-only correction of the paper's Eq. 14; `score_centering_logits_processor` in the engine's `logits_processor_func` slot (same slot as top-k distillation) emitting per-token `sc_correction` plus head-mass diagnostics; `score_centering_ppo_loss` wrapper selected in `engine_workers` when the flag is on. - `compute_policy_loss_reinforce` adds `A * sc_correction` after the IS weighting; `compute_policy_loss_bypass_mode` dispatches it; `ppo_loss` forwards it and logs the diagnostics. - FSDP engine: hook gated on `score_centering`; `logprobs_from_logits` runs without `inplace_backward` when score centering is on. - `RolloutCorrectionConfig.score_centering` with validation and three presets. AI assistance (Claude Code) was used; every changed line was reviewed and the tests above were run by the submitter. ### Checklist Before Submitting - [x] Read the Contribute Guide. - [x] pre-commit on changed files. - [x] Docs (`docs/algo/rollout_corr.md` §8) and example. - [x] CPU tests added; GPU smoke and the fp8-sampler reproduction above. - [x] CI request once ready. --------- Signed-off-by: cr-gao <gaochenrui@sjtu.edu.cn> Signed-off-by: Shawn/Yuxuan Tong <tongyuxuan361@gmail.com> Co-authored-by: Shawn/Yuxuan Tong <tongyuxuan361@gmail.com> Co-authored-by: Cursor <cursoragent@cursor.com>


This file contains hidden or bidirectional Unicode text that may be interpreted or compiled differently than what appears below. To review, open the file in an editor that reveals hidden Unicode characters.
Learn more about bidirectional Unicode characters
Sign up for free
to join this conversation on GitHub.
Already have an account?
Sign in to comment
1 participant

Add this suggestion to a batch that can be applied as a single commit.This suggestion is invalid because no changes were made to the code.Suggestions cannot be applied while the pull request is closed.Suggestions cannot be applied while viewing a subset of changes.Only one suggestion per line can be applied in a batch.Add this suggestion to a batch that can be applied as a single commit.Applying suggestions on deleted lines is not supported.You must change the existing code in this line in order to create a valid suggestion.Outdated suggestions cannot be applied.This suggestion has been applied or marked resolved.Suggestions cannot be applied from pending reviews.Suggestions cannot be applied on multi-line comments.Suggestions cannot be applied while the pull request is queued to merge.Suggestion cannot be applied right now. Please check back later.
No description provided.