Repository navigation

Replies: 1 comment 6 replies

|
If you are using this supervised approach in BERTopic, then it might be important to choose an algorithm that works generally well with class-imbalances, like XGBoost. Also, the evaluation metric here becomes more important since metrics such as accuracy tend to favor the majority class.
Indeed, the easier the topics are to separate, the easier they are to learn. That does not necessarily mean that you will have many documents per topic but it definitely does help. |

|
@MaartenGr I'm quite confused now. I've rerun the above model on a different part of my dataset, and the results for the classification have deteriorated significantly. I've created labels for the data based on .transform() of the unsupervised model I fitted on the original dataset, and then a .map() from those clusters to labels I want to see. Then training the classifier against those labels. Why would performance deteriorate so much? The number of docs is the same as before. The only thing I'm retraining is the Classifier and looking at the clusters created on this new dataset, they seem to make sense. |

|
It's difficult to say what is happening here. What do you mean by "deteriorating performance"? How do you define performance and how do you evaluate it? |
|
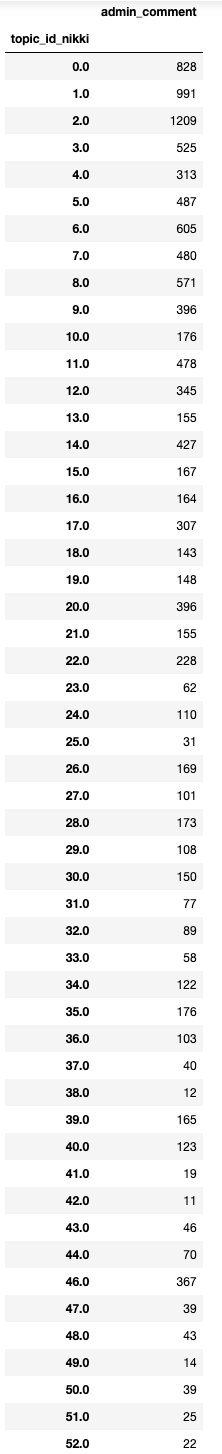
So my dataset is split like this across the multi-class classification I'm trying to run:
As I understand it, if we set umap_model = empty_dimensionality_model, then we will be using all dimensions of the embeddings we created? So I think that'd be 380 dimensions, ie. features. So with about 10,000 samples spread across 50 different topic id's as pictured, would that leave us open to the curse of dimensionality? Is that the first thing I need to think about controlling for here? What would you suggest? When I said 'deteriorated', it's because I had run this on another sample which was v. similar in size and distribution with strong results even on the test set, of about 80% average F1-score across the classes, now nothing is being correctly classified apart from 2 classes. So 0% score, I'm not sure what's happened, as it's essentially the same problem. So these were the steps:
|
|
@MaartenGr I am guessing this works now because the unsupervised and supervised algorithm were both trained on the SAME sample of data. |

|
Glad to hear that you solved the issue. Also, thank you for posting your solution here! |


Uh oh!
There was an error while loading. Please reload this page.
Uh oh!
There was an error while loading. Please reload this page.
Hey Maarten
I have a labelled dataset with the pictured characteristics, I am wondering how many documents I would need per topic, and also how balanced the dataset needs to be (have you observed some sort of threshold for both factors in your experience?): would this also be reliant on how similar the embeddings are for documents within each topic and how dissimilar they are to documents in different topics?
I wonder also how one would go about ensuring the minimum no. docs and the minimum requirements for balancing of classes is met systematically?
All reactions