Repository navigation

Replies: 1 comment 2 replies

|
Thank you for sharing this, sounds like an interesting use case!
A custom vectorizer is indeed what is typically used for these kinds of solutions. A nice example of this would be the POS tagger KeyphraseVectorizers which has implemented a tagger component of SpaCy as a vectorizer model. You could do the same with NER.
The one problem with such a heavy-compute vectorizer is that it can slow things down quite a bit when used in the CountVectorizer as it processes all individual documents. Instead, you could focus on NER as a |

|
Thanks for the quick reply. Will definetely check out the code KeyphraseVectorizers and see if I can put together something like that (perhaps without the transformer). Would be really nice to be able to integrate NER more smoothly into BERTopic. Perhaps experimenting with Promptify may alos lead somewhere... I will definetly look into combining NER with the representation_model. My intuition at this point is however that it is important to preform more complex keyword-extraction on document level - especially in more technical areas. Here is one example of that when used in a corpus containing 40k neuroscience research abstracts. |

Although that might be possible, the underlying vectorizer might not necessarily pick them up with specifying some additional parameters, like
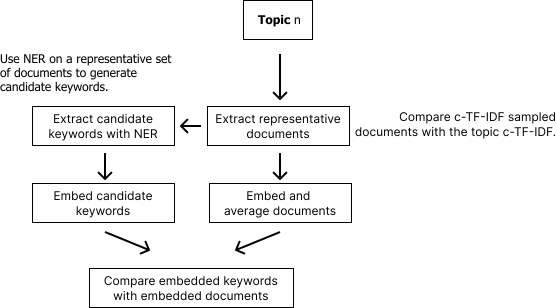
I think it would be possible to achieve similar performance with a fraction of the compute by calculating the named entities after the clustering with a representation model. The reason for this is that topic modeling is essentially an aggregation of documentations in a cluster. As such, not all named entities across all documents will be used for the resulting topic keywords and labels. What I have seen thus far, and which seems to hold true in many representation models, is that you only need a representative set of documents for each topic to extract the relevant keywords from. The number of representative set of documents is a parameter that can be tweaked. Going from having to calculate NER for hundreds of documents in a cluster to only a dozen or so speeds things up quite a bit. Arguably, this might even improve performance as the focus is more on those set of documents. In practice, I imagine it will be a cross between
|


Uh oh!
There was an error while loading. Please reload this page.
Uh oh!
There was an error while loading. Please reload this page.
Hi,
I've used the BERTopic approach in several research papers now embedding mainly research abstracts, but I decided to extract keywords using NER before creating topic representations with cTF-IDF.
(I published the fine-tuned NER model for extracting scientific methods/issues and other terminology https://huggingface.co/RJuro/SciNERTopic along with a Colab notebook that reproduces my pipeline).
So far, I'm reconstructing the BERTopic pipeline in ad-hoc notebooks. Such domain-specific keywords have lifted topic representation to a new level, IMO. In other areas they may enable new applications, e.g. clustering job-postings and representing by extracted skill-requirement mentions.
Is there a smarter way to integrate NER-based keyword-extraction into the pipeline?
Would that require coding up a custom vectorizer?
Thanks
Roman
All reactions