Repository navigation
Consuming too much time for Dynamic Topic Modeling on Google Colab #1056

Replies: 2 comments 8 replies

|
Generally, it should not run for that long of a time. For me, it typically runs within a couple of minutes. Could you share your full code? Also, did you make sure to set |

|
Hi Marteen, Sorry for the mistake, BUT the model I used for topic over time was used with BERTopic verison 0.12): topic_model = BERTopic(embedding_model="all-MiniLM-L6-v2",diversity=0.8,language="english", calculate_probabilities=True, n_gram_range=(1,3), verbose=True,top_n_words=20, nr_topics=15) '===== CODE used for topic over time who spent 19 hours (executed in Nov-2022) === '## Load the articles print(df.shape) '## The column 'tit_abs' is the one with title+abstract text pip install bertopic doc = df['tit_abs'].tolist() topic_model = BERTopic(embedding_model="all-MiniLM-L6-v2",diversity=0.8,language="english", calculate_probabilities=True, n_gram_range=(1,3), verbose=True,top_n_words=20, nr_topics=15) topics, probs = topic_model.fit_transform(doc) freq = topic_model.get_topic_info() '## Save model '## FOR TOPIC OVER TIME topics_over_time = topic_model.topics_over_time(doc,years)
topic_model.visualize_topics_over_time(topics_over_time) '##Save html topicover time I hope this help. Thanks, I really, really appreciate your time and support. |

|
It might be a combination of using |
|
I appreciate your suggestions and I will apply them to see the results and I will inform you. Greetings |
|
Hi Maarten, Do you have any suggestions to get 'clear' topic frequency development for text like abstracts? I use 70,000-130,000 articles for 7years?. I'm making tests with different configurations (outlier reduction), but I'm going to use global_tuning and evolutionary_tuning . But I appreciate any suggestions. |
|
I believe the |

|
Hi Maarten, ##main Code Create your representation modelrepresentation_model = MaximalMarginalRelevance(diversity=1) Reduce outliersnew_topics = topic_model.reduce_outliers(doc, topics)
|
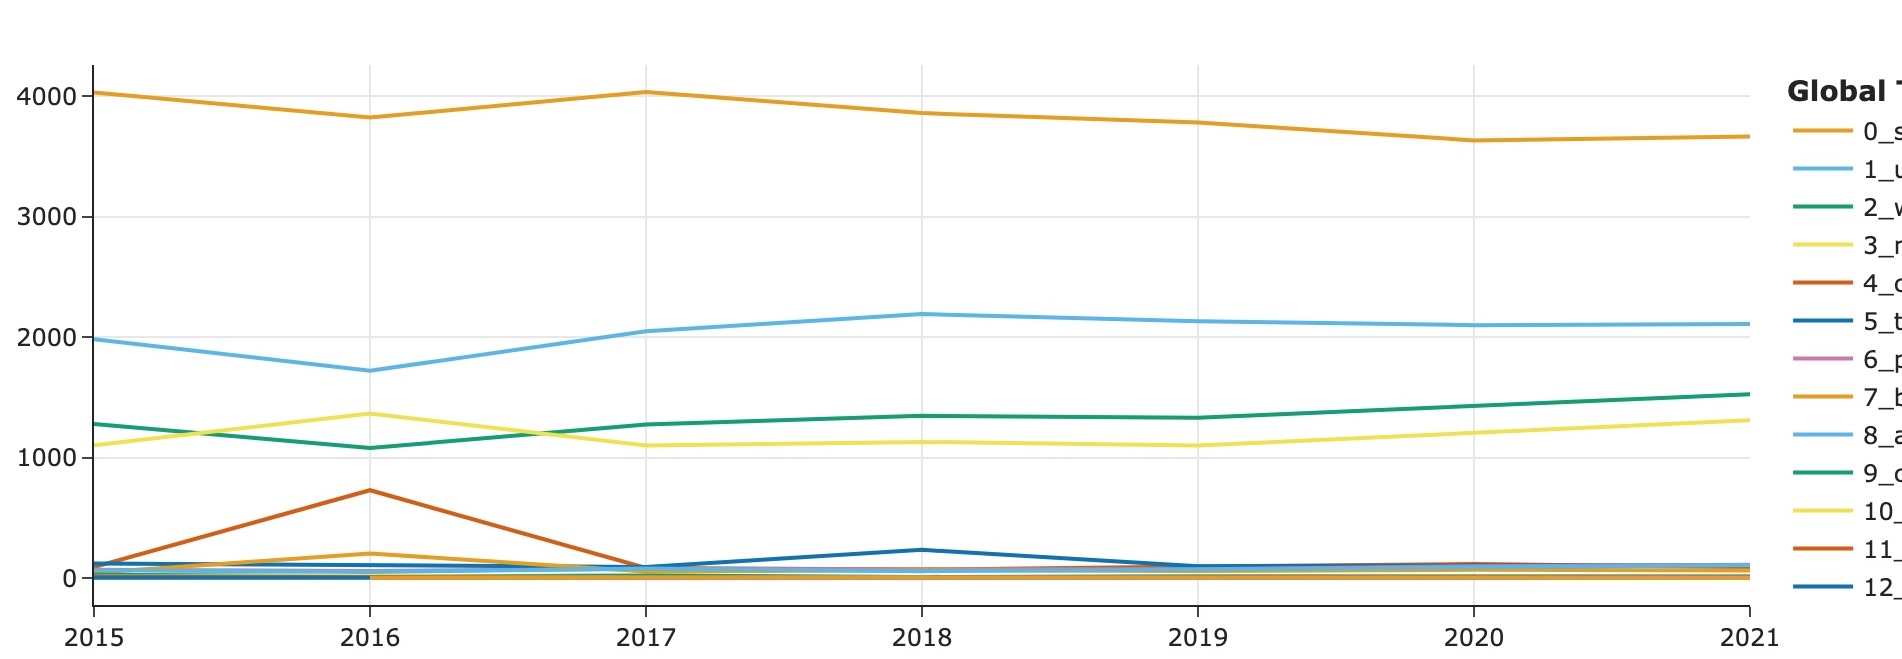
|
The stability that you refer to is the slope of the line, right? In that case, it is important to note that |


Uh oh!
There was an error while loading. Please reload this page.
Uh oh!
There was an error while loading. Please reload this page.
Hello Marteen,
I really love BERTopic but I have a question about time consuming for DTM.
I have 70,000 scientific articles (**Just ** Title+Abstract) from 2015 to 2021 (10,000 per year). Around 160 words per paper (mean) after stopwords.
I force to just 15 topics (nr_topics=16) and 20 words per topic. The time/date data is just the year on each article.
I use Google Pro+, but for a DTM run consumes around 15-20 hours.
The last one was for almost 20 hours:
7it [19:55:42, 10248.99s/it]
Is that a correct time consuming? Is there a way to reduce time consuming to save compute units =save $$ in Google Colab Pro+? My big issue is because I want to increase articles to 140,000.
Thank you very much in advance,
Roberto Carlos
All reactions